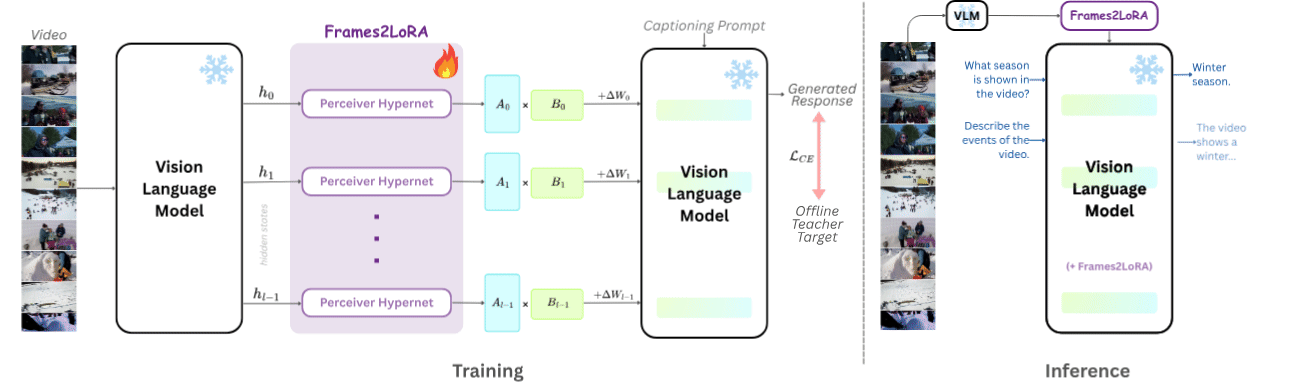
Turning a video into a LoRA adapter: Frames2LoRA explained
How Frames2LoRA turns a video into a LoRA adapter so a frozen vision-language model answers questions about it with zero visual tokens in context.
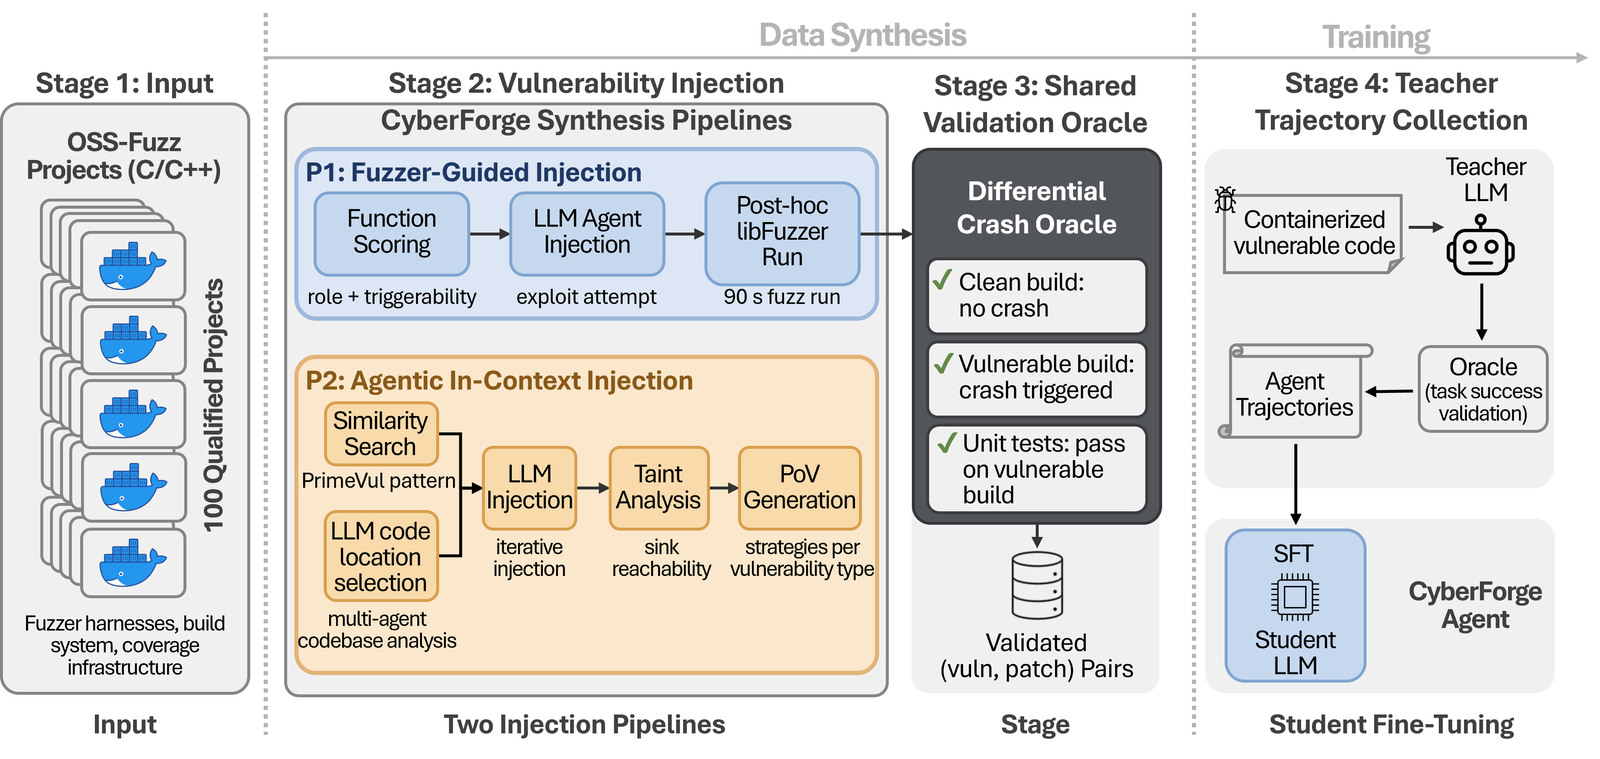
Manufacturing bugs that survive the test suite: CyberForge explained
How CyberForge injects execution-verified vulnerabilities into real C/C++ repositories, and what training on them does to a security agent.
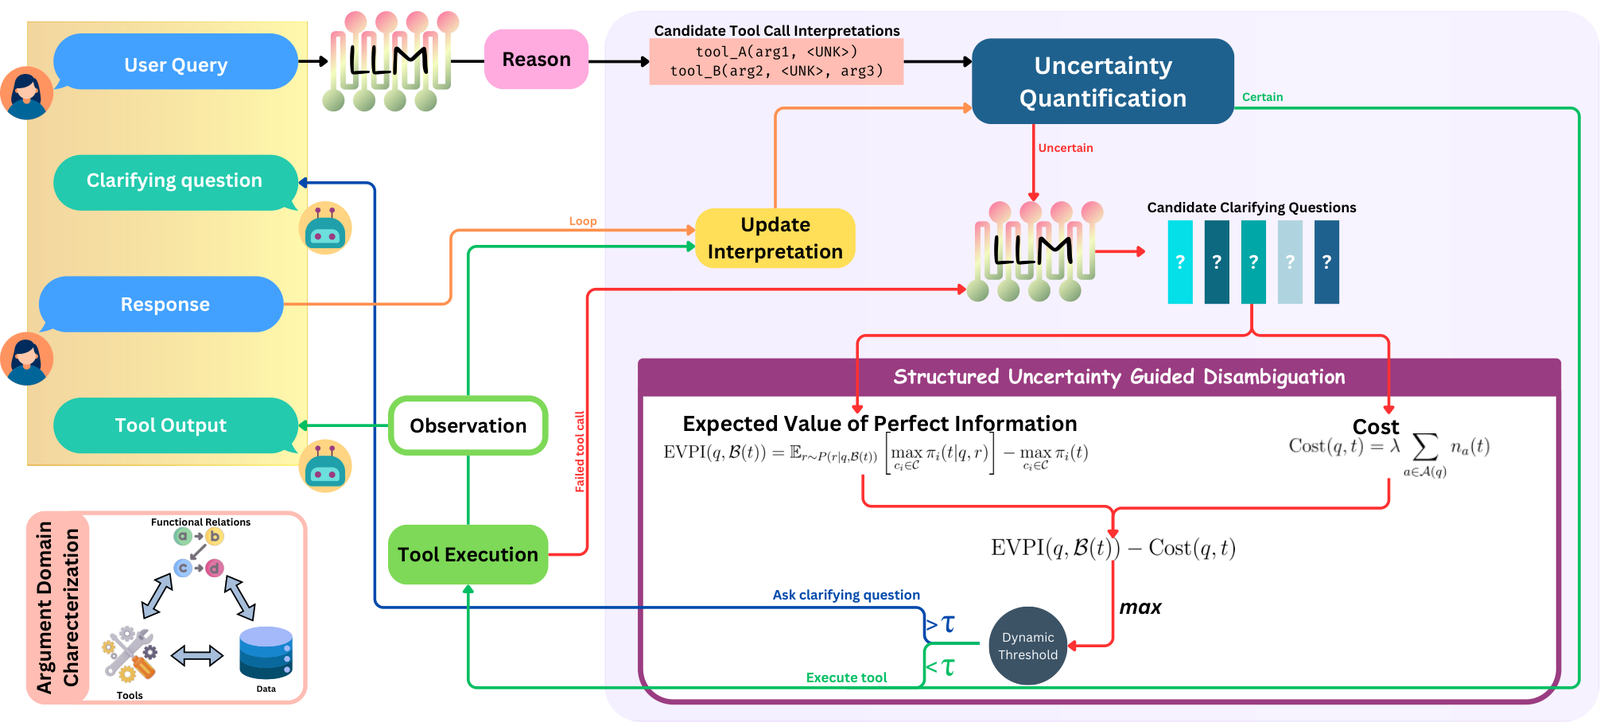
Ask fewer, better questions: SAGE-Agent and ClarifyBench explained
How modeling uncertainty over tool parameters, not tokens, lets an LLM agent decide which clarifying question to ask and when to stop asking.
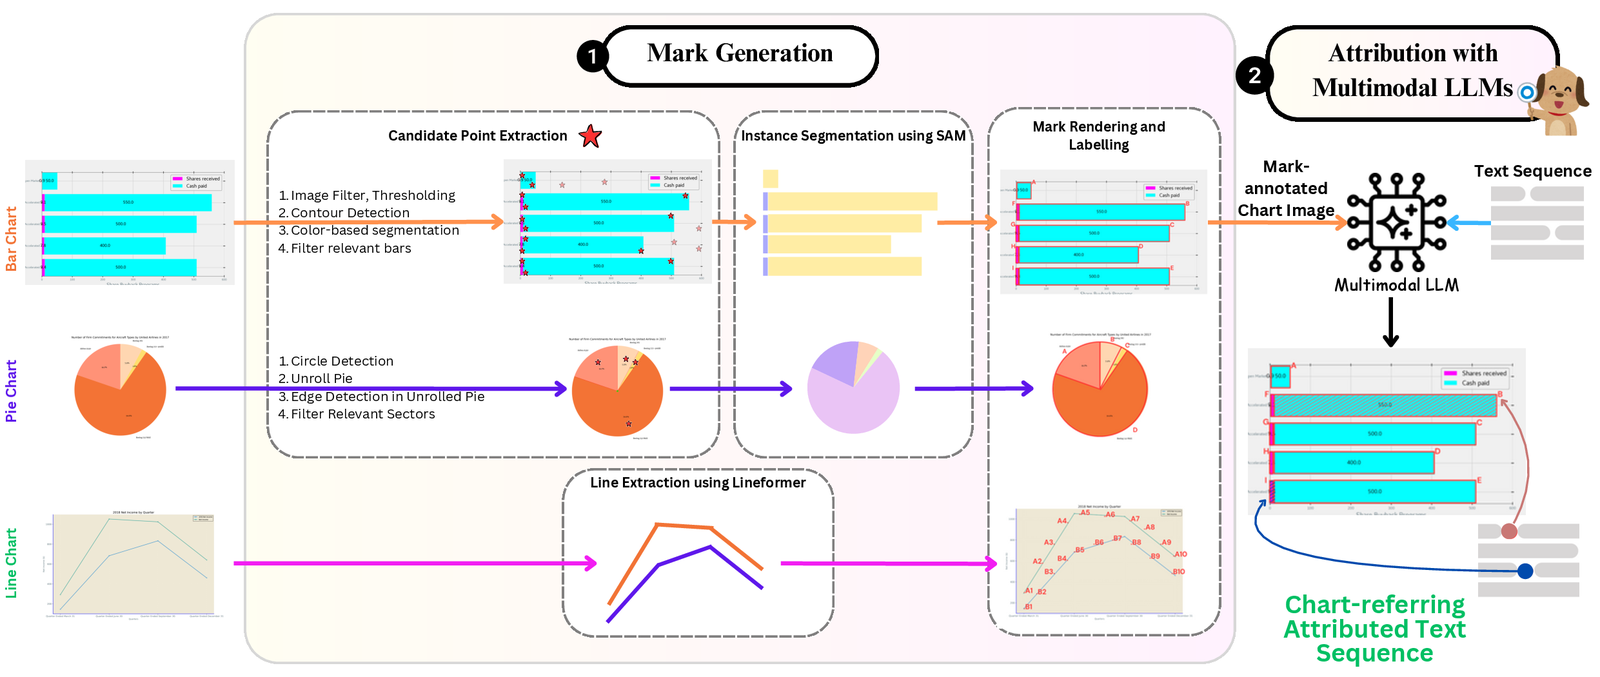
Which bar is the model talking about? ChartLens explained
How ChartLens grounds a multimodal LLM's chart answers to specific bars, points, and sectors, and why that makes hallucinations easy to catch.
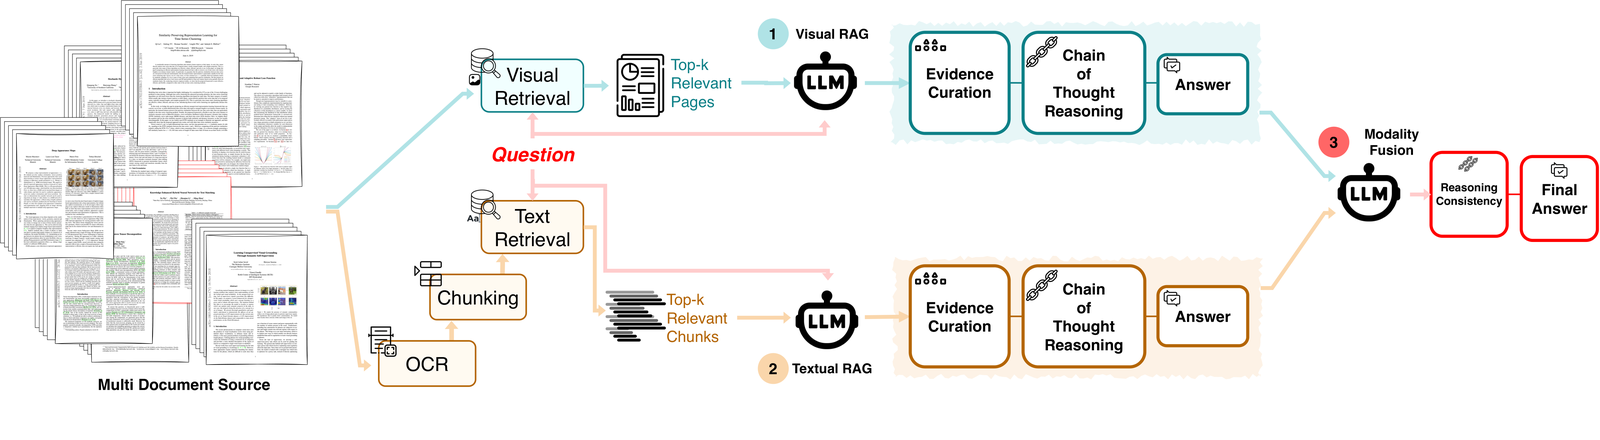
Answering questions over a pile of PDFs: VisDoM explained
Why multi-document QA breaks when the answer is in a table or a chart, and how VisDoMRAG fuses visual and textual retrieval to fix it.